The launch meeting
A product brief becomes three slides for the team the same morning, without spending an hour in a presentation app aligning columns that refuse to line up.
Your brief in PDF goes to two Text nodes that each write one slide, and GPT Image 2.5 Sunburst draws them in 16:9, text included. Workflow visible here, no account needed.
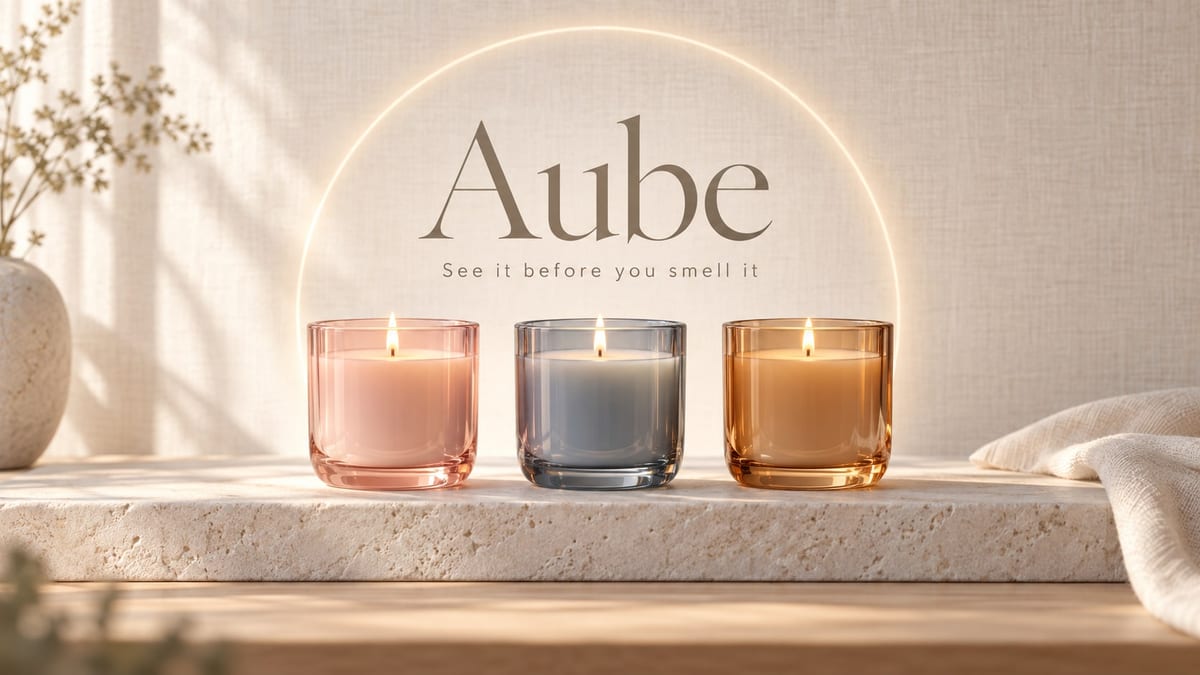
Real workflow: the launch brief of a candle brand, read by two Claude Sonnet 5 nodes that write the prompts, two slides drawn by GPT Image 2.5 Sunburst. Both images come from the demo.
At a glance
A presentation almost never gets stuck on ideas: it gets stuck on layout, palette, columns that refuse to line up. This workflow takes the document you already have, a brief, a memo, a report, and turns it into drawn slides, title and figures included.
The hard part fits in three words: text inside image. An image model writes about ten words cleanly, and invents letters beyond that. Both prompts in the demo therefore give the EXACT words to write between quotes and forbid everything else, which as a side effect produces slides that are more readable than average.
Both Text nodes read the PDF themselves, which means you can change document without touching a prompt. A full run costs less than thirty credits, and laying out a resume follows the same mechanics for a single page.
These are the files of the workflow above, exactly as the models produced them, unretouched. The starting point is shown when there is one.
Render
Product managers, freelancers and teachers who already have the document and do not want to spend the afternoon aligning columns.
A text PDF of one to ten pages, exported from a word processor: a scan cannot be read, the Text node would only see pixels.
Drop your document in
A text PDF, not a scan: the Text node reads content, not pixels. A brief, a framing memo or a three page report all work.
Let the Text node write the prompt
It does not summarise the document, it writes the image prompt of ONE slide: the exact words to write, the layout, the palette, the typography.
Force the small amount of text
The exact words between quotes, and a ban on writing anything else. That is the rule that separates a clean slide from an image full of fake words.
Re-read the numbers
An image model can shift a decimal. Ten seconds of reading before you present avoids the one mistake nobody forgives in a meeting.
The same canvas, tuned for different needs: each variation is two or three lines of prompt away.
A product brief becomes three slides for the team the same morning, without spending an hour in a presentation app aligning columns that refuse to line up.
A twenty page report nobody will read gives three screens everybody will look at: the title, the figures, the conclusion. The document stays the source, it is not rewritten.
Three numbers and three labels fit in one image, and that is exactly what an image model writes cleanly. It is the most useful slide of the set, and the safest.
A clean 16:9 title also works as an opening card in an edit, where a screenshot of a presentation app is spotted immediately.
A chapter gives one slide per idea, with the key words written large. For a whole illustrated set, the children's book shows the same mechanics over a run of pages.
The palette and the typography live in the prompt, so they do not drift from one slide to the next: two nodes, one brand, as many images as you want.
This is the mistake that breaks everything. Beyond about ten words the image model writes letters that do not exist. The exact words between quotes and nothing else: the constraint also makes better slides.
A scanned PDF is an image: the Text node reads nothing in it and invents a plausible presentation out of thin air. A text PDF exported from a word processor changes everything.
With no colours imposed, every slide goes its own way and the set falls apart. The palette goes into the prompt once, and is copied from node to node.
An image model redraws digits instead of copying them, and a decimal can move. It is the one mandatory check before you present.
No, the output is one image per slide, in 16:9. That is perfect to project, publish or drop into a document, and it cannot be edited text by text like an office file.
Duplicate the pair of nodes as many times as you need: each slide is one Text node and one Image node. The demo shows two to stay readable, the mechanics do not change at the tenth.
The Text node takes the numbers from your PDF, but the Image node redraws them, and that is where a decimal can move. Re-reading the figures on screen is the check that matters.
Twenty-four credits for the two slides in the demo: three credits per reading of the PDF, nine credits per image in high quality. One more slide is about a dozen credits.
GPT Image 2.5 Sunburst on a light slide, measured clean letter for letter. On a very dark flat background it returned black smears three times on 18 September 2026: Nano Banana Pro holds those backgrounds better.
Yes, by writing them into the prompt: the colour codes, the type family, where the title sits. The Text node will carry them into every slide since it reads the same instruction.
It goes to the model that reads it, like any attachment sent to an AI, and nothing is published. For a sensitive document, run the test on an anonymised version.
Yes, the prompt decides the language written on the image. Ask for the exact words in the language you want and the model writes them as they are.
Create a presentation with AI, from a PDF
Use this workflowFree account, no card required. The workflow opens pre-filled in your canvas.
 GPT Image 2.5 Sunburst
 Claude Sonnet 5
 Nano Banana Pro